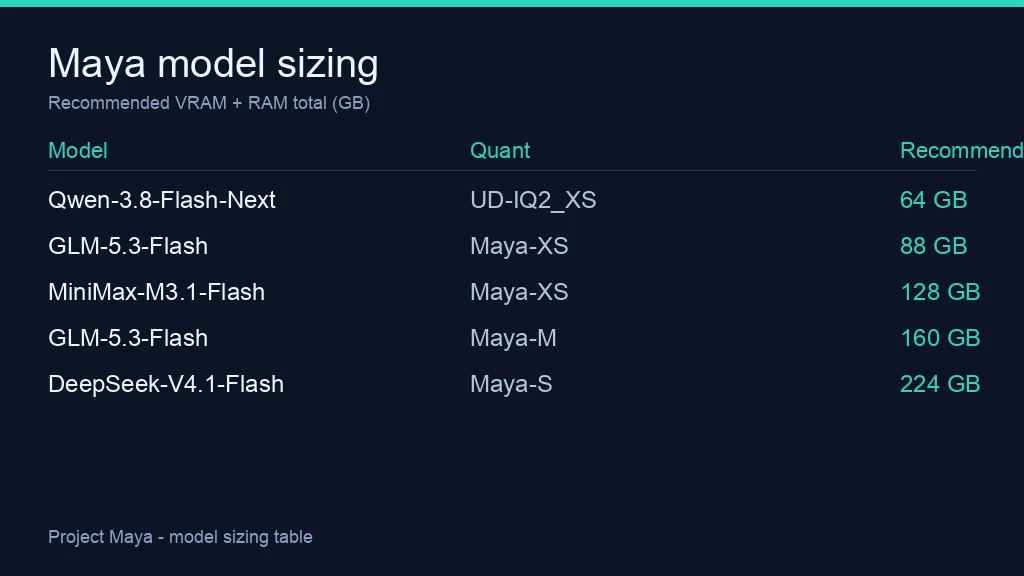
The size of a local model on your PC is decided by one number: VRAM plus system RAM. Maya keeps the most-used parts of the model on the GPU, the rest in RAM, and reads whatever does not fit from a fast NVMe SSD while it answers.
Two sizes are worth separating. *Whole model* is the memory the setup counts to keep every part of the model resident in VRAM and RAM. *Recommended* adds room for the operating system and the default context. Below the recommended size the model still runs, just slower, because the missing part is read from the SSD.
The sizing table
Sizes are in GB. "Whole model" is the memory needed to keep the entire model in memory; "Recommended" adds the system and the default context.
| Model | Quant | Whole model | Recommended (VRAM + RAM) | Runs on |
|---|---|---|---|---|
| GLM-5.3-Flash | Maya-XS | ~80 | 88 | NVIDIA, AMD, Mac* |
| GLM-5.3-Flash | Maya-S24 | ~102 | 128 | NVIDIA, AMD, Mac* |
| GLM-5.3-Flash | Maya-S (default) | ~104 | 128 | NVIDIA, AMD, Mac* |
| GLM-5.3-Flash | Maya-M | ~124 | 160 | NVIDIA, AMD, Mac* |
| GLM-5.3-Flash | Maya-L | ~164 | 192 | NVIDIA, AMD, Mac* |
| DeepSeek-V4.1-Flash | Maya-XS | 121 | 128 | NVIDIA, AMD |
| DeepSeek-V4.1-Flash | Maya-S (default) | 186 | 224 | NVIDIA, AMD |
| DeepSeek-V4.1-Flash | UD-IQ1_M | 140 | 160 | NVIDIA, AMD |
| MiniMax-M3.1-Flash | Maya-XS | 100 | 128 | NVIDIA, AMD |
| MiniMax-M3.1-Flash | Maya-S | 130 | 160 | NVIDIA, AMD |
| Qwen-3.8-Flash-Next | UD-IQ2_XS | 47 | 64 | NVIDIA, AMD |
| Qwen-3.8-Flash-Next | CYBER-FROST Q5_K_M | 84 | 96 | NVIDIA, AMD |
\* Mac (Apple Silicon) support is experimental and limited to the GLM-5.3-Flash GGUF quants. DeepSeek and Qwen ship n-gram tables that stay on the SSD and never count toward memory, so their download size is larger than the row suggests.
Matching a model to the machine you own
| Your PC | Total | Fits fully | Also runs, slower |
|---|---|---|---|
| 16 GB GPU + 48 GB RAM | 64 | Qwen UD-IQ2_XS | GLM Maya-XS, GLM Maya-S24 |
| 24 GB GPU + 64 GB RAM | 88 | GLM Maya-XS, Qwen UD-IQ2_XS | GLM Maya-S24, Qwen CYBER-FROST |
| 32 GB GPU + 96 GB RAM | 128 | GLM Maya-S, GLM Maya-S24, MiniMax Maya-XS | GLM Maya-M |
| 48 GB of GPUs + 128 GB RAM | 176 | GLM Maya-M, MiniMax Maya-S | GLM Maya-L, DeepSeek Maya-S |
| 64 GB of GPUs + 128 GB RAM | 192 | GLM Maya-L | DeepSeek Maya-S |
| 64 GB of GPUs + 192 GB RAM | 256+ | DeepSeek Maya-S, MiniMax EXL3 | DeepSeek UD-IQ3_S |
| Server with 384 GB RAM | 384+ | every model, DeepSeek UD-Q8_K_XL included | — |
On shared-memory machines such as a Strix Halo, a Gorgon Halo or a Mac, the memory is counted once and roughly 16 GB is left for the system. On a discrete card the split matters more: the same total is faster when more of it sits in VRAM rather than system RAM.
The floor
Every model still runs below its recommended size, as long as the machine has a supported GPU, 32 GB of RAM, and a fast NVMe SSD with room for the download. A hard disk is not a substitute.
What does not fit in VRAM plus RAM is read from the SSD while the model answers. That works, but the further below the recommended size, the slower it gets. The setup reports how much of the model it can keep in memory on your PC, so you can check the number before you commit to a multi-hundred-gigabyte download.
For the smaller end of the table, an RTX 4090 or an RX 7900 XTX paired with 64 GB of RAM is the classic one-big-model rig. A smaller card such as an RTX 4060 Ti is better paired with a Qwen UD-IQ2_XS build that fits fully in memory, instead of streaming from the disk forever.